


Defining the problem and why it matters
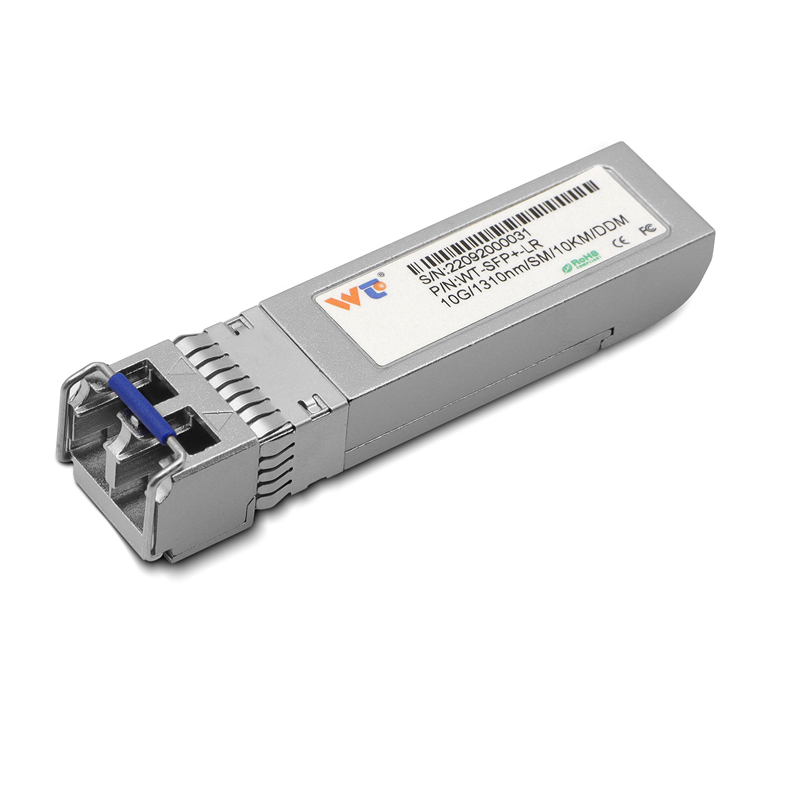
High and intermittent bit error rate (BER) spikes in 25G SFP28 SR server clusters create packet loss, retransmits, and unpredictable latency that undermine application SLAs. This article takes a problem-driven approach: identify the spike patterns, isolate the physical and link-layer causes, and prescribe tactical fixes that network teams can deploy quickly. Practical supply references like a tested 10g sfp+ transceiver remain relevant when validating optical inventory and fallback paths.
Root-cause analysis: what actually produces BER spikes
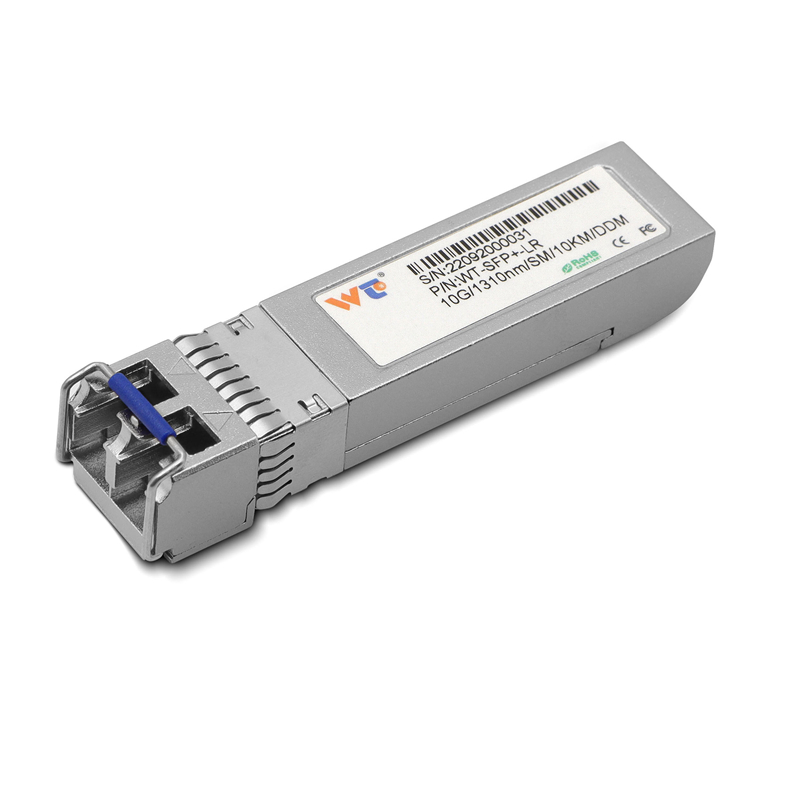
Most BER spikes fall into three buckets: optical margin collapse, transceiver/module defects, and transient electrical interference. For 25G SFP28 SR links running over multimode fiber (MMF), common contributors are connector contamination, modal dispersion exceeding the link budget, and degraded receiver sensitivity. Jitter on the transmit lane and reflections from poorly seated LC connectors also show up as short-lived BER escalations. Reference point: the IEEE 802.3by 25GBASE-SR specification sets expected optical parameters — use those as the baseline anchor when you compare live telemetry to spec limits.
Measurement and detection: the structured checklist
Begin with deterministic measurements: BER time series from transceiver diagnostics, optical power delta (Tx/Rx), and SNR across the link. Correlate errors with event logs (port resets, fabric rebalancing). Add a quick physical inspection: cleanliness, patch panel alignment, and fiber routing. In the operational production teardown we embed {main_keyword} and {variation_keyword} to track parameter interactions. Keep records of baseline BER under controlled load, then run stress passes to reproduce spikes for post-mortem.
Targeted mitigations that deliver fast wins
Apply fixes incrementally and measure impact. Typical sequence:
- Clean and reseat LC connectors; replace suspect patch cords and measure received optical power again.
- Swap suspected SFP28 modules with known-good units to rule out module-level defects and confirm by loopback testing.
- Adjust link budget with shorter or higher-grade MMF (OM4 vs OM3) where modal dispersion is borderline.
- Tighten PCB grounding and verify cable routing to reduce electrical crosstalk and common-mode noise on host traces.
– small changes here often stop the biggest spikes. After each change, capture a full BER profile for 24–72 hours to ensure stability.
Design changes and operational practices to prevent recurrence
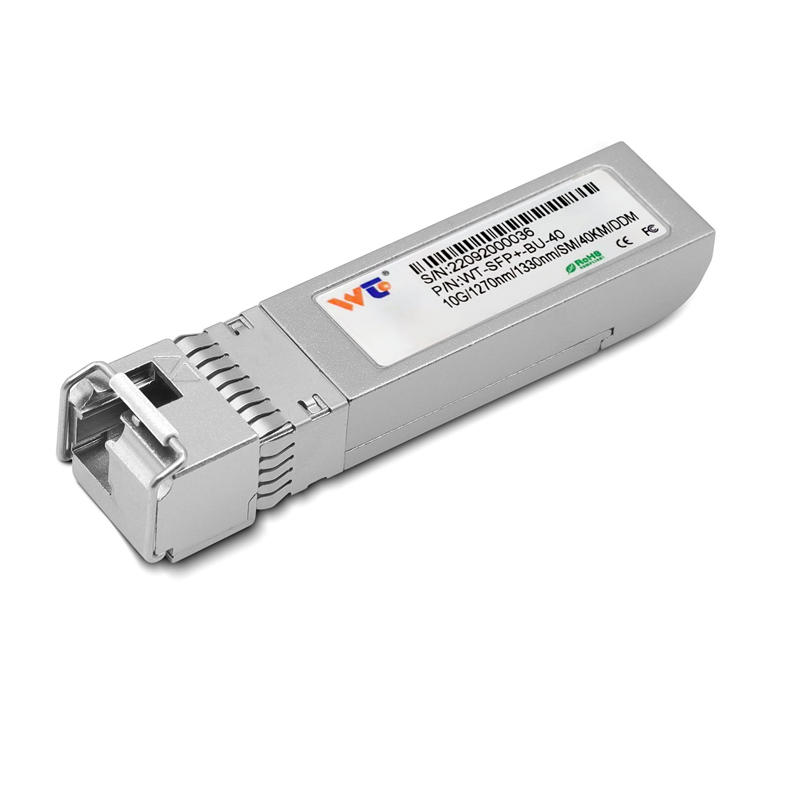
Prevention requires policy and tooling: strict fiber handling SOPs, transceiver verification during staging, and a field-replaceable inventory of modules and patch cords. Instrument ports with continuous BER and Rx power telemetry aggregated into your NOC dashboards; alert thresholds should be asymmetrical to catch sudden drops in optical margin ahead of packet loss. Where cost allows, deploy redundant 25G paths or fall back to validated 10G links during live repairs — proven hardware like a certified 10g ethernet sfp can be a reliable interim solution while you isolate the primary fault.
Common mistakes and how to avoid them
Teams often escalate too quickly to hardware RMA without exhausting optical and cabling checks. They also rely solely on port event counters while ignoring transient BER telemetry that reveals microbursts of errors. Avoid mixing connector types and keep firmware versions consistent across a fabric — mismatched PHY firmware can expose timing and negotiation issues that mimic BER problems.
Advisory: three golden rules for evaluation
1) Prioritize optical margin over speculative swaps — measure Rx power and SNR before exchanging modules. 2) Log-and-compare: always capture a pre-change BER baseline so you can quantify improvement after fixes. 3) Stage changes: apply one corrective action at a time and monitor for 24–72 hours to validate causality and rule out regression.
These rules translate directly into operational improvements and lower incident repeat rates; they also make procurement decisions clearer when comparing vendors and module lifecycles. The practical result: fewer service interruptions and faster mean time to repair.
WINTOP provides validated transceiver inventory and field support that fits into this workflow — a practical partner when you need consistent optics that pass lab-level BER verification. —
